Quickstart
Install, connect a model, and put an agent to work — in the terminal with
contenox-cli beam, or from the editor you already use. The shipped agent is ready
to use; declaring your own agent is optional.
To serve models to applications or other machines, follow Gateway: day one, then Gateway operations.
1. Install
Section titled “1. Install”CLI only. On Linux and macOS:
curl -fsSL https://contenox.com/install.sh | shOn Windows, in PowerShell:
irm https://contenox.com/install.ps1 | iexBoth install contenox-cli.
Or the IDE. Download and install the Contenox IDE package for your platform from contenox.com; it puts contenox-cli on your PATH.
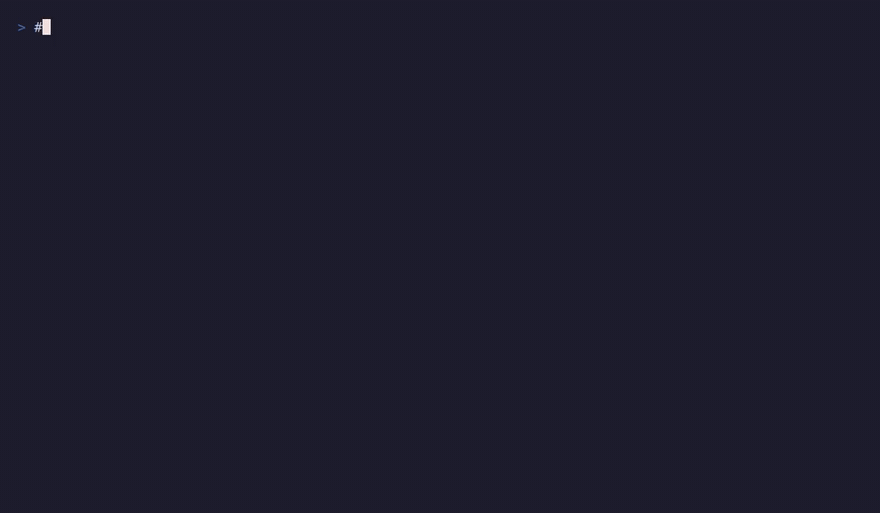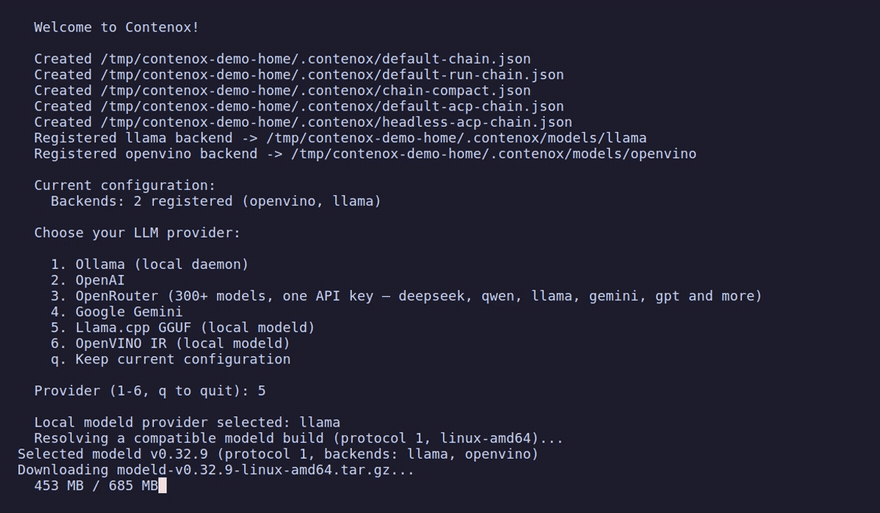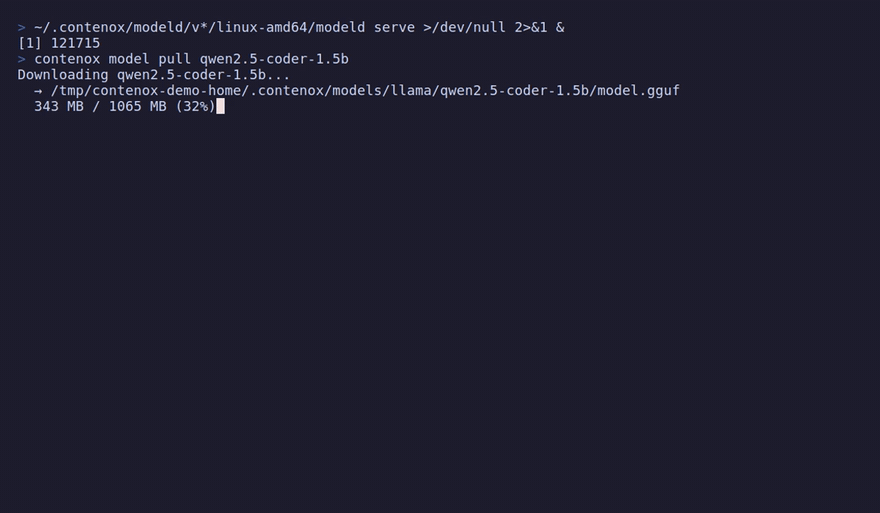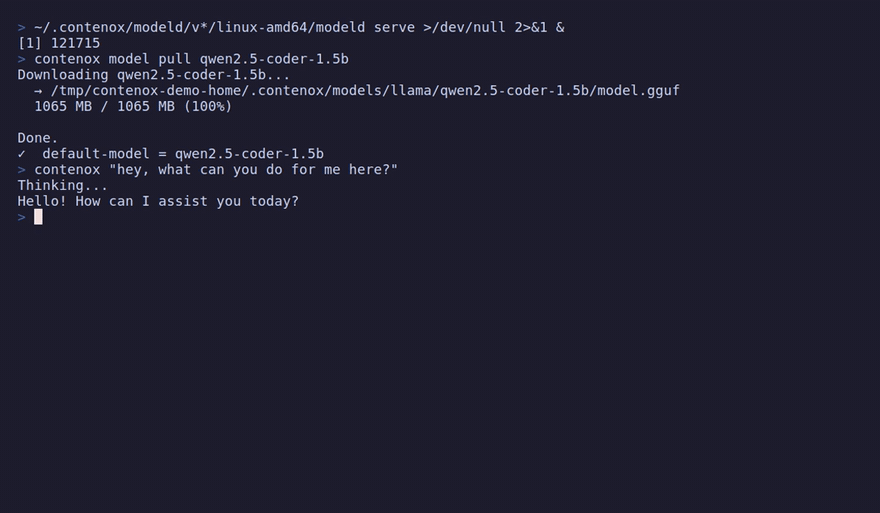
The whole path — install, setup, first prompt — in one take:
2. Connect a model
Section titled “2. Connect a model”From your project directory, set up native local inference:
contenox-cli autoContenox selects and downloads a model for available hardware and verifies tool
calling before saving it as the default. Selection prefers room for 128K–280K
hot context over larger model weights. Use contenox-cli auto --dry-run to inspect
the choice first. See local setup for
origin selection, download authentication and backend limitations.
contenox-cli setup offers manual provider and model selection, with modeld first.
For an existing Ollama installation, pull a model first:
ollama pull qwen3:8bcontenox-cli setup # pick Ollama, then pick your model from the listWhen Ollama is running, the wizard reads the models you have actually pulled and offers them as a numbered menu — press Enter to take the suggested one.
See the Ollama guide for details, including Ollama Cloud.
Then confirm the model is ready:
contenox-cli doctorIts first line is the verdict, and it names what to run next:
Ready: yes — run: contenox-cli beamIf it says Ready: no, the line under it names the one command that fixes it.
3. Start working
Section titled “3. Start working”contenox-cli beamRunning contenox-cli beam again returns to your latest session in the current directory.
A first terminal conversation with a local model — backends listed, then a question answered in place:
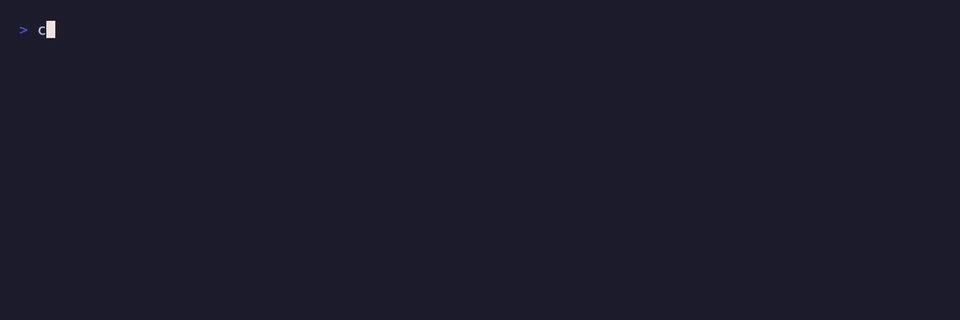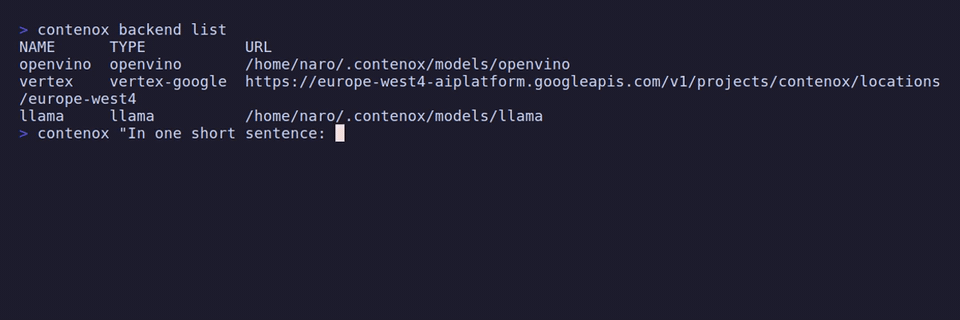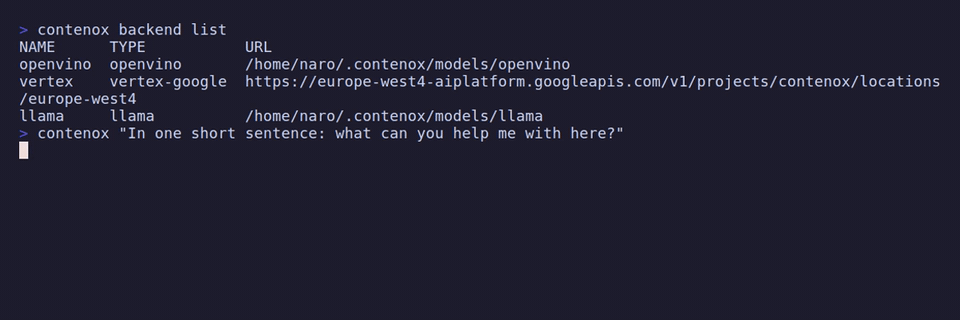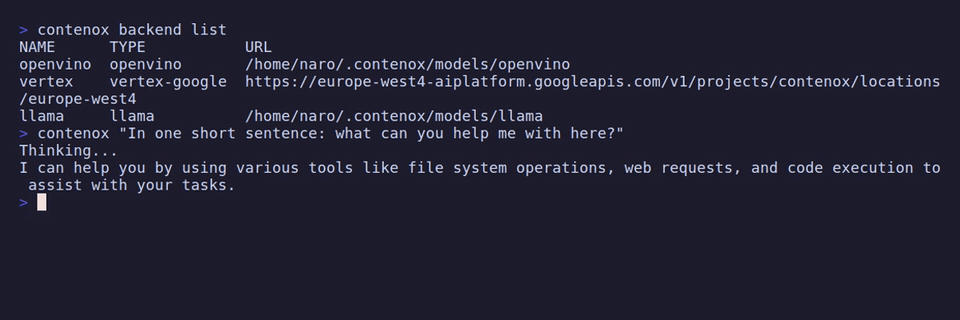
The transcript is your native terminal scrollback, so it scrolls, copies and searches the way everything else in that window does. The composer takes / for commands and @ to put a file in front of the agent. The status line carries the live model, the session, and how much context is left.
The first thirty seconds look like this:
- Type what you want —
@payments.go what breaks if the retry budget is exhausted mid-write?— and read the answer as it lands. Reads run silently; the shipped envelope allows them. - Ask for something that changes the world — a file written, a command run. The call stops in front of you as an approval card: the tool, the exact arguments, and the rule that gated it.
- Answer it with one keystroke. Approve and the call runs and the turn continues; deny and the agent is told so and works around it.
Nothing about that card is beam being careful. The envelope decided it before the surface saw it, so the same call gates the same way in an editor, or in a mission. That is the whole idea: see Human gates and envelopes.
Answering the card continues the same turn: the gated tool runs and the reply carries on. The ask was a durable row before the card appeared, so it is equally answerable from another terminal, it resolves to its on_timeout verdict if the wait runs out, and quitting checkpoints the run so you can answer it after reopening the session. See the durable ask.
Optional workspace configuration
Section titled “Optional workspace configuration”To create an explicit workspace marker and seed editable defaults:
contenox-cli initThis creates the project-local .contenox/workspace.id marker; agents/ and agents.toml are seeded into ~/.contenox/, shared by every project on the machine (contenox-cli init --local seeds workspace copies that shadow them instead). The approval envelopes are transpiled from agents.toml into ~/.contenox/.generated/, the shipped chains sit under ~/.contenox/system/; a workspace-local file with the same name overrides its global counterpart.
Optional custom agents
Section titled “Optional custom agents”An agent is one file. .contenox/agents/reviewer.md:
---name: reviewerdescription: Reviews a file for correctness problems---
You are a code reviewer. Read the file you are asked about, then list theproblems you can point at in what you actually read.
No build step — the next run picks it up:
contenox-cli agent listThe frontmatter says how to run it, the body becomes its system prompt. Budgets, retries and shell allowlists go in agents.toml beside it. See Declaring agents.
Scripted and background work
Section titled “Scripted and background work”Once the agent does what you want at the keyboard, the same declaration runs without you.
A program is the caller — CI, cron, a Makefile. contenox-cli run takes the task, prints the report to stdout, and exits 0 when the work landed:
contenox-cli run reviewer "review payments.go"contenox-cli run "summarise what changed under ./internal since Friday"With no agent named it runs the preseeded run declaration.
Or fire it and walk away. A mission is a one-line intent at a declared agent under a named envelope, with a durable record — reports, plan, and questions that survive the terminal you closed:
contenox-cli mission fire reviewer "review the payment retry change" --waitOptional editor use
Section titled “Optional editor use”Contenox also runs inside editor or desktop clients that speak ACP. The same agents, model config, tools, and HITL policy are used either way; per the protocol the editor owns the workspace, so a session works in the project you already have open:
Cloud providers
Section titled “Cloud providers”Contenox needs at least one model to work. Pick the option that fits:
| Option | What you need |
|---|---|
| Ollama | Ollama installed locally, or an Ollama Cloud key |
| Google Gemini | A free Gemini API key (no GPU) |
| OpenAI | An OpenAI API key |
| ChatGPT subscription | ChatGPT account with Codex access; device-code login enabled (experimental) |
| Anthropic | An Anthropic API key (Claude) |
| AWS Bedrock | An AWS account with Bedrock model access |
| Vertex AI | Gemini billed through your GCP project |
| vLLM / OpenAI-compatible | Any server speaking the OpenAI API (vLLM, LM Studio, …) |
For automatic local setup, use contenox-cli auto. Hosted providers remain available
through contenox-cli setup.
Upgrading an existing installation
Section titled “Upgrading an existing installation”contenox-cli init --update preserves your existing agent configuration. A v1
agents.toml may therefore retain [chain] token_limit = 131072 and the
max_tokens template’s 16384 fallback. Renaming settings does not remove
those values.
Use /settings in the session to inspect effective values. To let agents inherit
the configured context window, set [chain] token_limit = 0 in the applicable
agents.toml; keep a positive value when you want an explicit agent ceiling.
Workspace and per-agent overrides still apply. See agent configuration
and configuration before changing custom limits.
Next steps
Section titled “Next steps”- Your first agent — one file, what contenox builds behind it, and where the knobs are
- CLI reference —
beam,run,serve, and every flag - Missions — unattended runs, their envelopes, and the durable record they leave
- Declaring agents — the full frontmatter, skills, and the tools an agent brings with it
- Core concepts — how agents, chains, tasks, and tools fit together
- Writing a chain by hand — for the agent that has outgrown a declaration
- How contenox compares — working with existing APIs, declarations, and execution policy.
- MCP integration — connect external tools
- AI sovereignty & the EU AI Act — hosting, state, and oversight controls you own